Realistic Test Coverage Targets for AI-Generated Code
 Nov, 22 2026
You’ve got a shiny new GitHub Copilot or Amazon CodeWhisperer suggestion that looks perfect. It compiles, it runs, and it passes your basic unit tests. But here’s the kicker: traditional test coverage metrics like 80% line coverage are often dangerously misleading when applied to AI-generated code. If you’re treating machine-written snippets exactly like human-written ones, you’re likely flying blind on subtle logic errors that don’t crash but simply get the answer wrong.
The industry is waking up to this reality fast. As of late 2024, over 58% of enterprises were using AI for at least 20% of their new code. That’s not a niche experiment; it’s standard practice. Yet, many teams are still chasing arbitrary percentage targets that haven’t been updated for the unique failure modes of Large Language Models (LLMs). This guide breaks down what actually works, why the old rules break, and how to set targets that keep your production environment stable without burning out your QA team.
Why Traditional Coverage Metrics Fail AI Code
Let’s be honest about what "coverage" actually measures. Standard tools like Istanbul or Jacoco tell you if a line of code was executed during testing. They do not tell you if the code did what you intended. For human-written code, we assume the developer understood the requirements before typing. For AI-generated code, that assumption is shaky.
AI models are probabilistic. They predict the next most likely token based on patterns, not logical understanding. This leads to specific failure modes that high coverage percentages miss entirely:
- Plausible but Wrong Logic: The code runs fine but calculates the wrong tax rate because the AI hallucinated a business rule.
- Missing Edge Cases: The AI generates a clean happy path but ignores null inputs or boundary conditions because they weren't in its training data context.
- Inconsistent Error Handling: A study by Codacy in 2024 found that AI-generated error handling fails in 32% of cases. Your tests might cover the success path, giving you 90% coverage, while leaving the entire failure mechanism untested.
If you stick to the old "80% is good enough" rule, you’re essentially gambling that the AI didn’t make a semantic error in the 20% of lines you didn’t deeply inspect. With AI, those semantic errors are more frequent than with humans.
Setting Realistic Targets: The Risk-Based Approach
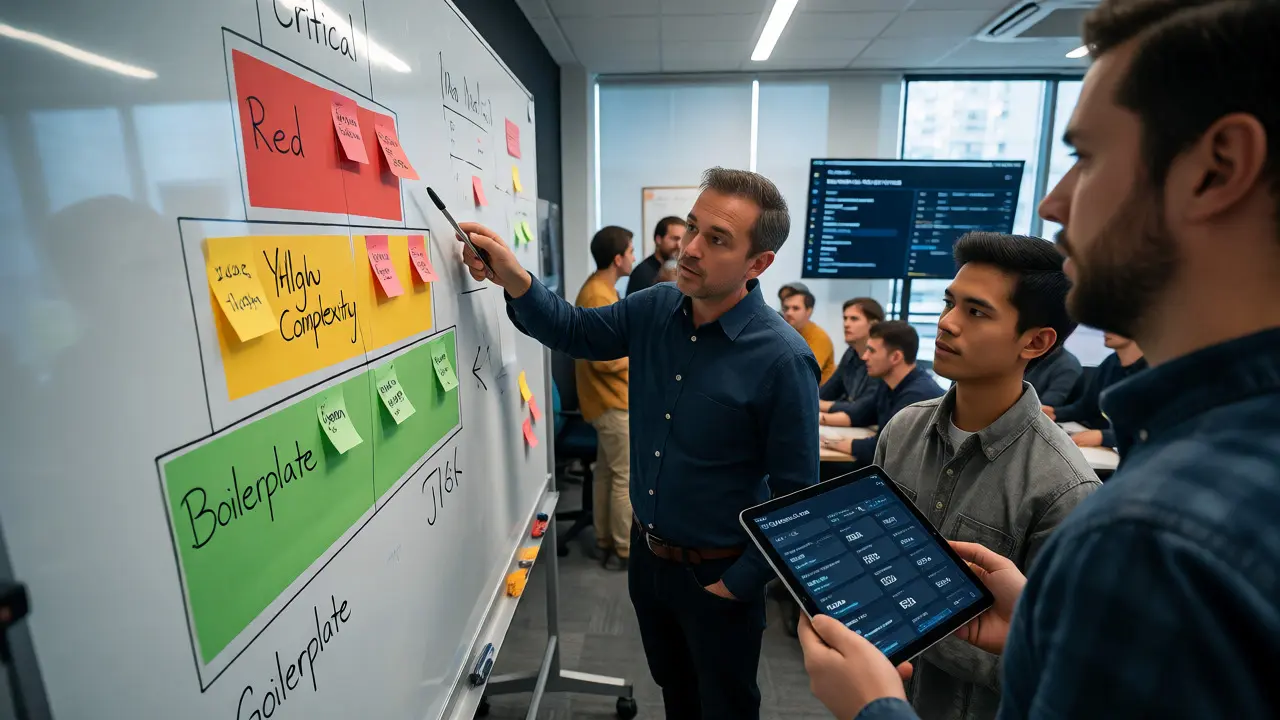
There is no single magic number. Setting a rigid global target like "95% coverage for all AI code" usually results in bloated test suites that are hard to maintain. Instead, successful teams use a tiered, risk-adjusted model. Think of it as triage.
| Risk Category | Target Line Coverage | Additional Requirements | Examples |
|---|---|---|---|
| Critical Path | 95-100% | Mutation Score > 75%; Manual Review | Payment processing, security auth, core financial calculations |
| High Complexity | 90-95% | Edge case testing; Property-based testing | Data transformation pipelines, complex algorithms, API integrations |
| Boilerplate/UI | 70-80% | Snapshot testing; Visual regression | CRUD forms, static UI components, logging utilities |
| Prototyping | N/A | Manual verification only | Spike solutions, throwaway scripts, internal tools |
Notice the shift? We aren't just asking "did it run?" We’re asking "is it robust?" For critical paths, such as anything touching money or user identity, you need near-total coverage. For boilerplate code-where AI shines because it’s repetitive and predictable-you can relax. Trying to force 95% coverage on a simple React component generated by AI is a waste of engineering time.
Beyond Coverage: Mutation Testing and Semantic Validation
If coverage tells you if code ran, Mutation Testing tells you if your tests actually work. It involves automatically introducing small bugs (mutations) into the code and seeing if your tests catch them. If you have 90% coverage but a low mutation score, your tests are shallow.
For AI code, this is non-negotiable. Experts from Graphite recommend a minimum mutation score of 75% for AI-generated modules. Why? Because AI often generates defensive coding that never triggers. You might have an `if` statement checking for a condition that never happens. Your test covers the line, but it doesn’t prove the logic is sound. Mutation testing exposes these "zombie" branches.
Additionally, consider Metamorphic Testing. This technique checks if properties of the output remain consistent even when input changes. For example, if you sort a list, reversing the input should result in a reversed sorted output. AI often struggles with these invariant properties, making metamorphic tests highly effective at catching logic errors that standard assertions miss.
Practical Implementation Steps
How do you actually roll this out without disrupting your workflow? Here’s a three-phase approach used by teams transitioning to AI-assisted development.
Phase 1: Identification and Tagging
You can’t test what you can’t find. Use tools like SonarQube or GitHub’s native attribution features to flag which parts of your codebase are AI-generated. In recent versions, SonarQube flags AI code with roughly 92% accuracy. Create a metadata tag in your build system so you know which files require stricter scrutiny.
Phase 2: Risk Scoring
Not all AI code is created equal. Implement a lightweight risk scoring system. Does the file touch the database? Does it handle user input? Is it part of the checkout flow? Assign a risk score (Low, Medium, High) to each AI-generated module. This determines the coverage threshold applied in your CI/CD pipeline.
Phase 3: Automated Enforcement
Update your pull request templates and CI checks. If a PR modifies a "High Risk" AI-generated file, fail the build if coverage drops below 95% or if the mutation score falls under 75%. For "Low Risk" files, enforce standard 80% coverage. This prevents developers from gaming the system by adding trivial tests to hit a global average.
Common Pitfalls and How to Avoid Them
Even with good intentions, teams fall into traps. Here are the big ones seen in the field:
- The False Confidence Trap: Teams see 95% green coverage bars and assume the code is safe. Remember the retail company that lost $2.3M because their AI pricing logic had 80% coverage but missed a holiday discount boundary condition. Coverage does not equal correctness.
- Test Flakiness: AI-generated tests can sometimes be brittle. If you use AI to write the tests too, verify they aren't relying on unstable external states. A common complaint on HackerNews is increased flakiness when AI writes integration tests without proper mocking.
- Maintenance Overhead: Chasing percentage points increases maintenance costs. Forrester notes that rigid targets can raise maintenance costs by 22% with marginal quality gains. Focus on covering critical paths rather than every single utility function.
The Future: Dynamic Quality Indices
We are moving away from static percentages. By 2027, experts predict that fixed coverage targets will become obsolete. Tools are already emerging that calculate a "Comprehensive AI Code Quality Index," combining coverage, mutation scores, and logical correctness validation. Microsoft’s upcoming Visual Studio updates hint at this direction, replacing simple coverage numbers with holistic health scores.
Until then, stay pragmatic. Use higher coverage for risky AI code, rely on mutation testing to validate those tests, and don’t let perfect be the enemy of good for boilerplate tasks. The goal isn’t to punish AI; it’s to treat it like a junior developer who types fast but needs careful code review and thorough testing.
Is 80% test coverage still acceptable for AI-generated code?
Generally, no, not for critical business logic. While 80% may suffice for simple boilerplate or UI components, research indicates that AI-generated code requires higher thresholds (90-95%) to achieve defect escape rates comparable to human-written code at 80%. The risk of subtle logical errors is higher, necessitating deeper validation.
What is mutation testing and why is it important for AI code?
Mutation testing introduces small bugs into the source code to check if existing tests detect them. It is crucial for AI code because high line coverage can exist even if tests are weak or superficial. A high mutation score proves that your tests actually validate behavior rather than just executing lines, catching cases where AI generates plausible but incorrect logic.
How do I identify which parts of my code are AI-generated?
Many modern IDEs and linters now support AI attribution. GitHub Copilot offers attribution features, and tools like SonarQube can flag AI-generated segments with high accuracy. You can also enforce commit message conventions or use pre-commit hooks to tag files modified by AI assistants, allowing your CI/CD pipeline to apply different coverage rules accordingly.
Does AI-generated code need different types of tests?
Yes. Beyond standard unit tests, prioritize edge-case testing and property-based testing. AI often misses boundary conditions and error handling scenarios. Metamorphic testing, which verifies that outputs change consistently with inputs, is particularly effective at catching logical inconsistencies in AI algorithms that standard assertions might miss.
Should I use AI to generate tests for AI-generated code?
It can be helpful but requires caution. AI test generators can quickly create boilerplate tests and find obscure edge cases. However, they can also produce false positives or flaky tests. Always review AI-generated tests manually, especially for critical paths, and supplement them with mutation testing to ensure they provide real value.